Organize Files
Duplicates: Same Name, Same Size, Same File?
Find duplicate files by their contents, state which copy to keep, and quarantine the rest so they can be restored.
Lesson 6 of 18 in the recommended order · About 25 min (estimate)
On this page
Workflow automation glossary — terms and common confusions
- Dry run
- A run that reports every change it would make and makes none of them.
A dry run that still writes a log file, sends a message, or creates a folder is not a dry run.
- Idempotent
- Running it again leaves the same result as running it once.
"It did not crash the second time" is not the same property; check what the second run changed.
- Run record
- The stored facts about one execution: when it started, what it read, what it changed, how it ended.
A run record is not the log. The log is prose for a person; the record is data the next run reads.
- Transient failure
- A failure that a later identical attempt could succeed at, such as a timeout.
A rejected record and a dropped connection are not the same failure, and retrying the first one forever is a bug.
- Backoff
- Waiting longer between successive retries instead of retrying immediately.
Backoff without a maximum attempt count is an unbounded loop with a politeness delay.
- Request budget
- A hard cap on how many requests one run may make, checked before each request.
A page limit is not a budget if a retry can make extra requests the limit never counts.
- Quarantine
- Setting aside a record a run could not process, with the reason, so the run continues.
Quarantine is not "skip". A skipped record leaves no trace; a quarantined one is countable and reviewable.
- Reconciliation
- Showing that the counts in a report add up: read equals processed plus quarantined plus rejected.
A report whose totals cannot be reconciled is a summary of what the code believed, not of what happened.
- Trigger
- The event or time that causes a run to start.
Scheduling a trigger is a decision made on a machine, not something a browser lesson can install for you.
- Heartbeat
- A signal a healthy run emits, whose absence is itself the alert.
Alerting only on errors cannot detect the job that stopped running at all, which is the most common outage.
- Staleness
- How old the most recent successful run is, compared with how old it is allowed to be.
A green last run is not freshness. Ask when it ran, not whether it passed.
- Atomic replace
- Writing output to a temporary name and renaming it into place in one step.
A reader never sees a half-written file; an interrupted run leaves the previous output intact.
- Transport
- The injected callable that actually performs a request, separate from the client that interprets it.
A client that builds its own connection cannot be tested without a network, which is why the seam exists.
- In-memory filesystem
- The filesystem this course’s browser exercises operate on, which lives only inside the tab.
It behaves like a filesystem and is not your disk: nothing an exercise writes exists after the run ends.
Outcome
By the end of this lesson you can decide which files in a folder are genuinely copies of one another by comparing their contents, choose which copy to keep according to a rule you have written down, and move the others somewhere they can be brought back from.
Why it matters
"Remove the duplicates" is one of the most common automation requests and one of the easiest to get catastrophically wrong, because the word duplicate is doing several jobs at once.
Four files, in one folder:
report.csvandreport (1).csv— identical contents. Genuinely one file, saved twice.report.csvandreport-final.csv— different names, identical contents. Also one file.march.csvandmarch.csvin two different folders — same name, and one is last year's.notes.txtandnotes.txt— same name, same size, one character different. Somebody's correction.
A deduplicator that matches on names deletes the wrong ones in the third case and misses the second entirely. One that matches on size deletes a correction. The only thing that establishes two files are the same file is that their contents are the same, and the only cheap way to establish that across a folder is to hash them.
The second half of the request is the dangerous half. "Remove" can mean delete, and deletion cannot be undone by this job. A move into a fresh quarantine folder can be reversed if no destination is overwritten and the original path is recorded. An unchecked move can overwrite an existing file, so a real job must protect each destination before moving.
Concept
Four ways to decide two files are the same, in increasing order of how much they prove:
- Same name: Proves nothing about the contents. Misses copies saved under different names.
- Same size: A useful cheap filter, but proves almost nothing. Misses two files of the same size with a different character.
- Same hash: Extremely strong evidence of the same bytes. A rare collision remains possible; compare bytes when the stakes require it.
- Same bytes: Proves the contents are the same. A full byte comparison of every candidate pair costs more work.
A cryptographic hash such as SHA-256 turns any file into a fixed-length value, and two files with the same hash have, for every practical purpose, the same contents. It is worth being precise about why this is enough rather than treating it as magic: a deliberately constructed SHA-256 collision is not known to be achievable, and an accidental one has never been observed. If you are deduplicating files that a hostile party controls and the stakes are high, compare the bytes of the candidates the hash grouped together. For a folder of scans and spreadsheets, the hash is the evidence.
import hashlib

def content_hash(path):
    digest = hashlib.sha256()
    with path.open("rb") as handle:
        for chunk in iter(lambda: handle.read(65536), b""):
            digest.update(chunk)
    return digest.hexdigest()
Two details make this usable on real files. "rb" reads bytes, not text: a text-mode read decodes, may fail, and can normalise different line endings into the same text. Two files with different bytes can therefore appear equal after text normalization; hashing the bytes preserves the distinction. Reading in chunks means a 4 GB file uses 64 kB of memory rather than 4 GB.
Size is worth using as a prefilter: group by size first, hash only within groups of more than one. Files of different sizes cannot be identical, so this skips most of the reading in a large folder. It is an optimisation, not a decision — the hash still decides.
Which copy do you keep? This is a policy, not a fact, and the job must state it. Reasonable rules include: the one in the preferred folder; the oldest, as the original; the newest, as the corrected one; the shortest name, since report.csv beats report (1).csv. All are defensible; picking one silently is not. Write the rule where a reader can disagree with it, and make the job report which copy it kept.
Quarantine, do not delete. Move the other copies into a folder named for the run — quarantine/2026-09-08/ — and leave a note of where each came from. This gives you three things a delete does not: somebody can look at what was removed, anything wrong can be put back, and the folder itself is the record of what the run did. Deleting the quarantine folder later is a separate, boring decision that a person makes on purpose.
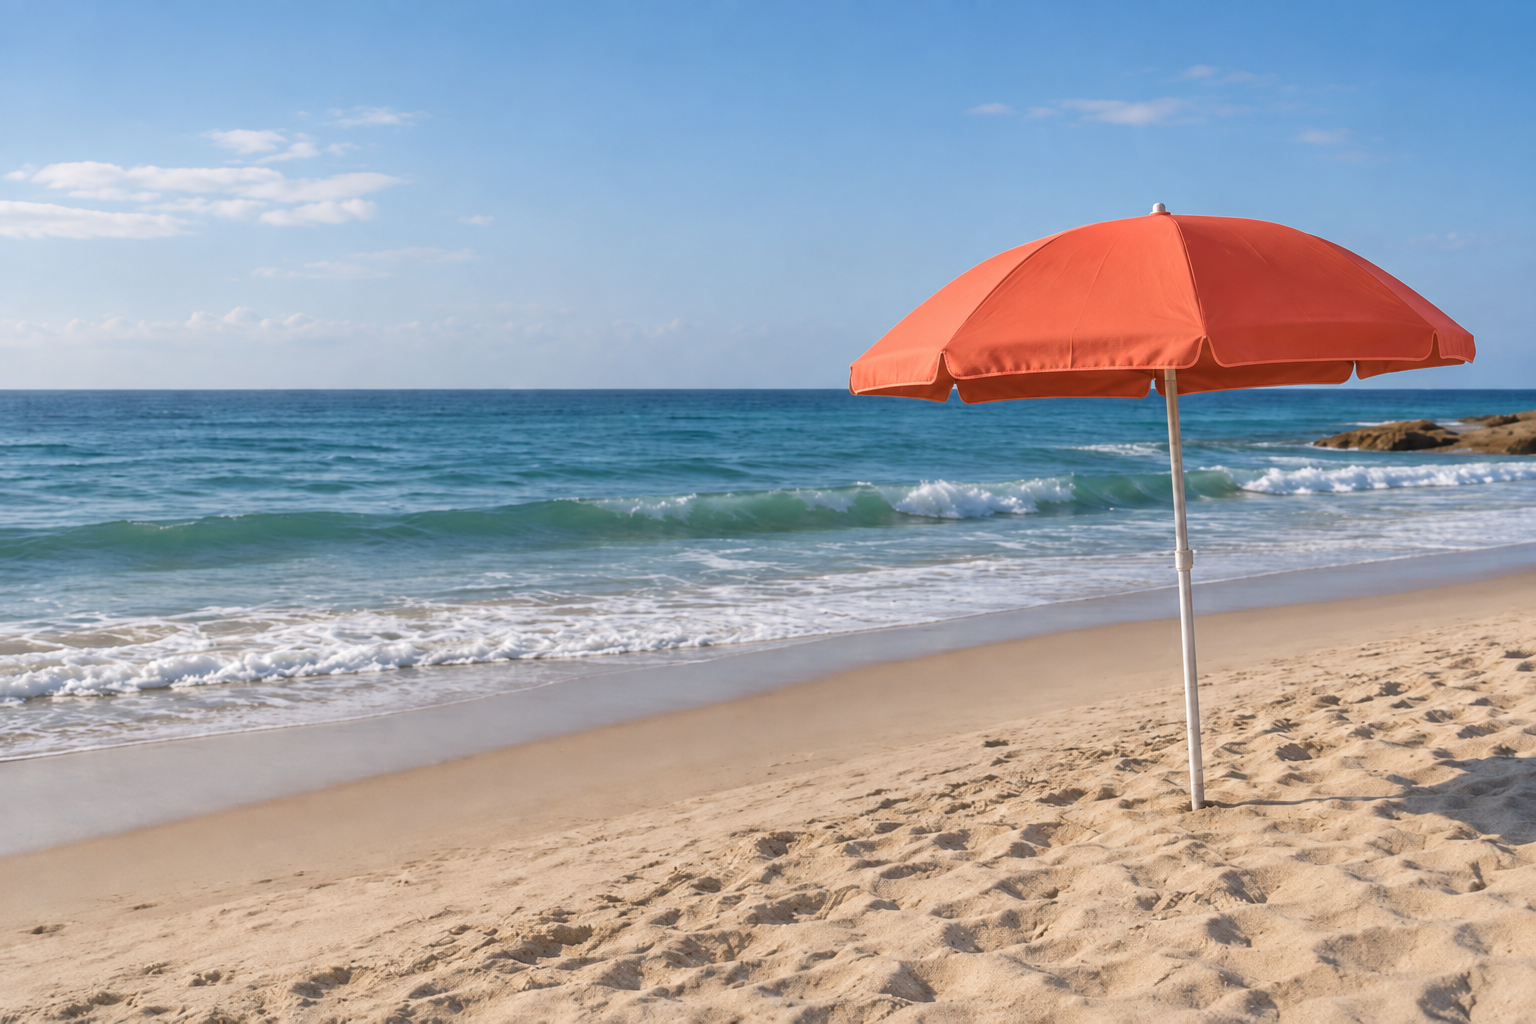
Try a file comparison. These fictional generated beach pictures are a separate sample from the text-only browser exercise below. One file was copied byte for byte under another name; a similar picture was generated with a coral umbrella. Other scene details changed too. Predict which two downloadable files will have the same SHA-256 hash, then compare their measured bytes.
Compare the three sample files
Names and appearances do not decide byte identity
Original · g04-beach-original.png
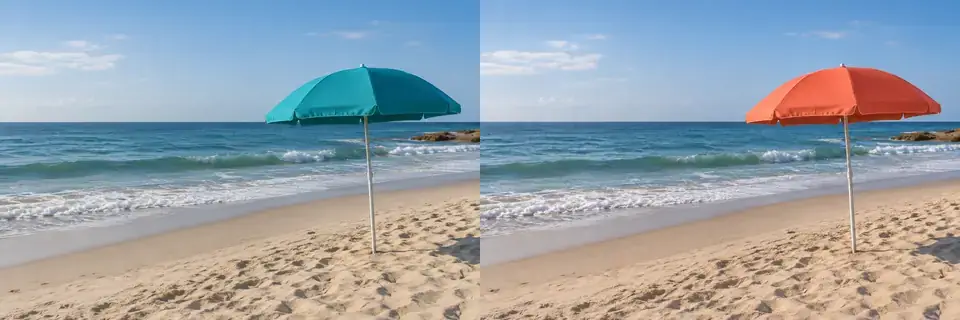
Download size- 2,348,653 bytes
SHA-256- bcb4030d fe4f5673 68307469 fd86d8e4 b356fd76 d52a99fa 9ad3a28f 9b51972b
Original generated PNG. This measurement belongs to the downloadable PNG, not the small preview.
Exact copy · g04-beach-copy.png
Download size- 2,348,653 bytes
SHA-256- bcb4030d fe4f5673 68307469 fd86d8e4 b356fd76 d52a99fa 9ad3a28f 9b51972b
A filesystem copy of the original PNG: same bytes and hash, despite the new filename.
Edited variant · g04-beach-edited.png
Download size- 2,256,690 bytes
SHA-256- 741df421 e69a02fc ff69d568 258595f1 93266323 de266de0 e09043f0 85aafd28
A generated edit changes the umbrella color. Other scene details also differ; this is not a pixel-isolated recolor. The measured file is not byte-identical.
Download the exact measured PNG files: original beach picture, byte-identical copy under another name, and edited beach picture. These downloads are optional; the small image crops above come from a separately encoded preview pair, so their own byte lengths and hashes differ from the PNG measurements shown.
Read the code
import hashlib
import pathlib
import tempfile

root = pathlib.Path(tempfile.mkdtemp()) / "photos"
root.mkdir(parents=True)
for name, body in [
    ("beach.jpg", "AAAA"),
    ("beach copy.jpg", "AAAA"),
    ("sunset.jpg", "BBBB"),
    ("beach-edited.jpg", "AAAB"),
]:
    (root / name).write_text(body, encoding="utf-8")


def content_hash(path):
    digest = hashlib.sha256()
    with path.open("rb") as handle:
        for chunk in iter(lambda: handle.read(65536), b""):
            digest.update(chunk)
    return digest.hexdigest()


groups = {}
for entry in sorted(root.iterdir()):
    if entry.is_file():
        groups.setdefault(content_hash(entry), []).append(entry.name)

print("files:", sum(len(names) for names in groups.values()))
print("distinct contents:", len(groups))
for names in sorted(groups.values()):
    keep, *rest = names
    print(f"keep {keep}" + (f", duplicates: {', '.join(rest)}" if rest else ""))
groups.setdefault(hash, []).append(name) is the same grouping idiom the previous lesson used for rename targets, applied to a different key. Building the whole grouping before deciding anything is again what makes the decision reviewable.
keep, *rest = names takes the first name in the sorted group as the one to keep. That is the stated policy — first name in sorted order wins, not necessarily the shortest name — and it is visible in one line where somebody can argue with it.
beach-edited.jpg differs from beach.jpg by one character and therefore hashes differently, which is the whole point: a size comparison would have called them the same.
Predict the output
Predict every line.
Check your prediction
files: 4
distinct contents: 3
keep beach copy.jpg, duplicates: beach.jpg
keep beach-edited.jpg
keep sunset.jpg
Three groups, because beach.jpg and beach copy.jpg hold identical contents while beach-edited.jpg differs by one character.
The line worth stopping at is the first one. Within the group, names were appended in sorted order, and "beach copy.jpg" sorts before "beach.jpg" — a space is character 32, a full stop is 46 — so the "keep the first" policy keeps the copy and marks the original as a duplicate. The policy did exactly what it says; what it says is not what anyone meant.
That is the honest reason to write the keep rule down: this one is defensible as an alphabetical tiebreak and indefensible as "keep the original", and only the written rule tells you which one the job is claiming to do.
Modify the code
Replace content_hash(entry) with entry.stat().st_size as the grouping key.
What changes, and why
files: 4
distinct contents: 1
keep beach copy.jpg, duplicates: beach-edited.jpg, beach.jpg, sunset.jpg
All four files are four bytes long, so size puts them in one group and the job would quarantine three files, two of which are not copies of anything — including the edited version, which is the only file in the folder whose contents nobody else has.
Real folders make this worse rather than better. Files from one source tend to share sizes: scans at a fixed resolution, exports with the same number of rows, thumbnails. Size is a good prefilter precisely because it groups plausible candidates, and a disastrous decision for exactly the same reason.
Debug the bug
An assistant was asked for "a script to clean up duplicate files in my downloads folder". It produced this.
def deduplicate(folder):
    seen = {}
    removed = 0
    for entry in folder.rglob("*"):
        key = (entry.name.lower(), entry.stat().st_size)
        if key in seen:
            entry.unlink()
            removed += 1
        else:
            seen[key] = entry
    print(f"removed {removed} duplicate files")
What's actually wrong
It deletes files, and the rule it deletes them by does not establish that they are duplicates.
- The key is name plus size, and neither is evidence. Two files with the same name and size can differ in their contents — a corrected document is the everyday case. This deletes the correction and keeps the original, or the reverse, depending on traversal order.
rglob("*")crosses folder boundaries.2025/march.csvand2026/march.csvhave the same name and often the same size. The whole reason they are in separate folders is that they are different, and this treats the second one it meets as a duplicate of the first.unlink()is not recoverable. There is no quarantine, no report of what was removed, and no way to answer "what did it delete last night" other than noticing something is missing.rglob("*")yields directories too, andentry.stat().st_sizeon a directory returns a number, so a folder can be entered intoseenand — if a second folder matches —unlink()is called on a directory, which raisesIsADirectoryErrorpartway through a run that has already deleted files.- Which copy survives is decided by traversal order, and there is no stated policy at all.
A safer plan-and-move shape for an isolated folder, with a new quarantine destination for this run:
def plan_deduplication(folder):
    """Group files by contents and choose one to keep per group. Deletes nothing."""
    groups = {}
    for entry in sorted(folder.iterdir()):
        if entry.is_file():
            groups.setdefault(content_hash(entry), []).append(entry.name)
    keep, quarantine = [], []
    for names in sorted(groups.values()):
        keep.append(names[0])
        quarantine.extend(names[1:])
    return keep, sorted(quarantine)


def apply_deduplication(folder, quarantine_dir, quarantine):
    """Move to a new quarantine directory; refuse an existing destination."""
    quarantine_dir.mkdir(parents=True, exist_ok=False)
    for name in quarantine:
        os.replace(folder / name, quarantine_dir / name)
    return len(quarantine)
Contents decide, the keep rule is one visible line, and planning is separate from applying. exist_ok=False stops this version before moving if the quarantine directory already exists. That matters because os.replace silently overwrites an existing destination file. This example still assumes no concurrent writer can add a colliding name during the move; a real unattended job needs collision-safe move semantics, a per-run manifest and recovery handling for partial moves.
Try it yourself
The starter builds an inbox folder and an empty quarantine folder in the in-memory filesystem. Write group_by_content, plan_deduplication, and apply_deduplication: group by contents, keep the first name in each group, and move the rest into quarantine.
Loading this exercise…
Practical challenge (optional)
Optional, and the transfer task for this lesson: make the quarantine tell you where things came from.
Extend the apply step to write a small manifest.csv into the quarantine folder recording, for each moved file, its original name, its content hash, and the name of the copy that was kept. Then answer the question the manifest exists for: given only the quarantine folder, could somebody put every file back where it came from?
What a good answer looks like
They can if the manifest records the original path, not just the name — a quarantine folder collecting duplicates from several source folders will otherwise contain two entries called march.csv and no way to tell which came from where. That is the same collision the previous lesson refused, arriving from a different direction, and the same answer applies: detect it in the plan, before the move.
The stronger version writes the manifest before moving anything, then moves. A manifest written afterwards describes a run that has already happened, and is missing exactly the entries for the moves that failed.
Sign in to track your progress on this exercise.
AI collaboration
Checkpoint
- Why is "same name and same size" not evidence that two files are duplicates?
- What does reading in binary mode protect against when hashing?
- Why quarantine duplicates rather than delete them?
- Your job keeps
report (1).csvand quarantinesreport.csv. Is that a bug?
Answers
- Neither is about the contents. Two files with the same name and size differ whenever one is a correction of the other, and files from a single source frequently share a size. Only the contents establish that two files are the same file.
- A text-mode read decodes the bytes and can normalise different line endings into the same text, so byte-different files can appear equal; invalid text may fail to decode. Binary mode hashes what is actually stored.
- Because this job has no undo for deletion. In the isolated exercise, a move to an empty quarantine preserves the file bytes and gives somebody a folder to inspect. On a real disk, restore also needs the original path recorded and any destination collision prevented.
- Only if the stated rule was "keep the original". If the stated rule is "keep the first name in sorted order", the job did what it says and the rule is the thing to argue with. The bug is having no written rule, because then there is nothing to check the behaviour against.
Sign in to track your progress on this exercise.
Summary and next step
Contents decide whether two files are the same; names and sizes only suggest candidates. Hash in binary, in chunks, using size as a prefilter rather than a decision. Write down which copy you keep and why, so the behaviour can be disagreed with. Move the rest into a new, collision-protected quarantine folder rather than deleting them, so a wrong keep decision can be reversed. The next module moves from whole files to what is inside them: records that do not match the shape the job was promised.